Home Technology IT Services Can Your IT Stack Survive a Ma...
CIO Bulletin
,
21 October, 2026
Author:
CIO Bulletin Team
We live in a highly connected digital world where downtime is a lot more than just a minor inconvenience. Honestly, it is a massive financial drain that can fundamentally alter the trajectory of a business. Modern organizations rely entirely on incredibly complex networks of servers, applications, and databases. These systems serve customers and keep the daily operations humming along.
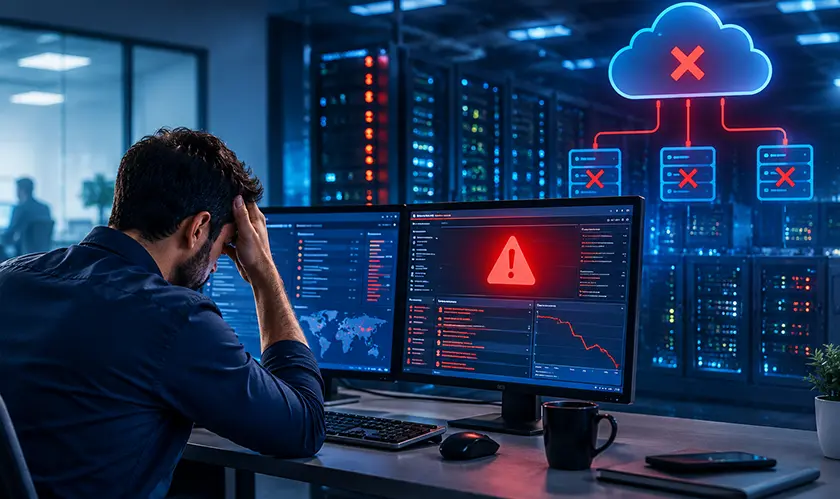
But what happens when the screen just goes dark? No warnings. Just silence.
There is a very specific, quiet dread that washes over a room when the primary servers stop responding. I guess panic usually sets in right after that. It is no longer a question of if a major outage will occur. It is exactly when it will happen. Severe weather events happen all the time. Critical hardware degrades over the years. Routine software updates frequently introduce unexpected bugs that cascade through the network. Your organization needs to know exactly how the infrastructure will respond when the absolute worst-case scenario becomes reality. Preparedness is the only thing that separates resilient companies from the ones that make headlines for all the wrong reasons. Let's look closer at what this really means.
Many business leaders severely underestimate what a system failure actually costs their organization. Are you really prepared, or just hoping for the best? They usually calculate the immediate loss of direct sales and stop right there. But they rarely factor in the thousands of hours wasted by employees who simply cannot do their jobs without access to internal tools. They completely forget about the severe reputational damage and the fragile customer trust that evaporates in a matter of minutes.
Just gone.
You pour your heart into building these customer relationships, and watching them fail over a technical glitch feels deeply personal. Getting things back online is a frantic race against the clock. Internal technical teams are often stretched far too thin managing daily operations to build and maintain an airtight recovery infrastructure on their own.
To bridge this critical gap, forward-thinking organizations often rely on managed disaster recovery to ensure their vital operations can resume quickly. You know, this approach guarantees that a dedicated, highly tested strategy is ready to deploy the exact moment a crisis hits. You need a secondary environment that perfectly mirrors your critical functions and can take over seamlessly.
And if you are scrambling to figure out your response strategy while the main server is actively down? You have already lost the battle.
The costs will continue to multiply by the second. Regulatory fines might apply if data becomes unavailable. Service level agreements with enterprise clients might be breached. So the financial impact of a prolonged outage can easily reach millions of dollars before the root cause is even identified. It is exhausting, honestly.
Every technological system has a breaking point. Your primary job is to find that breaking point before an unexpected outage does. Single points of failure love to hide in plain sight. You might have redundant servers but route all their external traffic through a single physical switch. You might have excellent data backups but store them on the same physical network segment as your primary customer databases. True resilience requires a thorough, unforgiving audit of exactly how your different components interact with one another.
You need to carefully map the intricate dependencies between your various applications. If your customer portal stays up but the backend payment gateway crashes, is the customer experience still intact? Definitely not. Having redundancy means having backup components waiting on standby. Having resilience means your architecture can automatically shift heavy workloads away from failing components without requiring immediate human intervention. You have got to design the entire network for inevitable failure. Expect the primary storage drive to corrupt. Expect the regional data center to lose power during a storm. Build the digital pathways that allow your operations to flow effortlessly around the blockage instead of hitting a solid brick wall. This kind of proactive thinking saves businesses.
Having a secure copy of your data is just the starting point of a survival strategy. Or at least, that is what we tell ourselves. A pristine backup is completely useless if it takes three full days to restore it to a functional state. How much data can you actually afford to lose? Recovery Time Objectives and Recovery Point Objectives are the specific metrics that actually matter here. You have to determine exactly how quickly the systems must be fully operational again. Answering these difficult questions requires brutal honesty from executive leadership.
Many companies boast loudly about their daily encrypted backups but consistently fail to test the actual restoration process. Discovering a corrupted backup file during an active emergency is a terrifying nightmare scenario. We have all been there, staring blankly at a dashboard full of red alerts, wondering how everything broke at once. You must test the restore process regularly and rigorously. Run unannounced fire drills. Simulate a total catastrophic loss of your primary data center and measure exactly how long it takes to spin up the secondary environment. Document every single failure that occurs during the test and fix those bottlenecks immediately. The recovery plan is truly only as good as its last successful test. Furthermore, the rise of sophisticated malicious software means your backups must be isolated from the main network. And if a virus encrypts your primary servers, it will likely try to encrypt your attached backups as well. It is crucial to maintain air-gapped backups to prevent this from happening.
Technology alone cannot save an organization during a major catastrophic event. The human element is equally critical to survival. Your technical team needs a very clear chain of command and highly detailed, well-documented procedures. Everyone must know their specific role the moment the red alerts start flashing on the dashboard. Confusion always breeds unacceptable delays. Clear alternative communication channels must be established entirely outside of your primary network.
If your internal email servers go down today, how will your team coordinate the complex recovery efforts?
Consistent training is absolutely essential. Engineers should practice failing over systems until the entire process becomes second nature. Leadership must actively support these initiatives and allocate the necessary financial resources to make them happen. Disaster preparedness is an essential investment in the long-term survival of the business. It requires continuous attention, regular funding, and constant adaptation as your underlying infrastructure evolves over time. When new software is deployed, the recovery plan must be updated to reflect that change. Failing to update the plan is basically planning to fail.
Major outages will eventually test the foundation of your business. You cannot control the unpredictable external events that cause complex systems to fail. But you can absolutely control your planned response to those events. A robust, well-tested recovery strategy transforms a potential company-ending catastrophe into a minor operational hiccup. Evaluate your current capabilities today. Identify the glaring gaps in your armor and start closing them immediately. Your future self will thank you when the unexpected inevitably happens.
Being prepared is the ultimate competitive advantage in a world that relies entirely on constant connectivity.


 consultants ltd.jpg)


Comments