Home Technology Software Lexis Solutions – Transformi...
CIO Bulletin
,
24 October, 2026
Author:
Sambhrant Das
Today, real-time web intelligence is at the heart of modern company strategy. But collecting web data on a large scale brings tough technical problems that are much more than simple extraction. Companies must handle changing site layouts, strict compliance rules, and anti-scraping tools. This needs special technical setups and strong know-how. If company data pipelines are not reliable or well-built, analytics systems break down. This hurts decision-making and weakens the company's position in the market. In a world where good information means survival, getting structured, permission-based web data is key to steady business growth.
The engineering philosophy of Lexis Solutions, an AI-native company involved in software development and data engineering that is committed to converting disordered online information into clear and useful context, goes beyond the use of strict, pre-made extraction tools. As a technology leader based in Bulgaria, the company develops intelligent data pipelines, custom scraping systems, and agentic workflows that are specifically designed for complicated corporate settings. Lexis Solutions achieves this by combining its Anthropic-certified knowledge with a partner-focused approach, thereby making sure that enterprise knowledge systems, retrieval structures, and automated systems are provided with reliable, uninterrupted, and production-quality data streams.
Lexis Solutions focuses on the development of agentic AI, the creation of custom web scraping systems, and the integration of multimodal applications, thereby enabling global entrepreneurs, digital leaders, and product teams in Europe and North America. The company's multidisciplinary team brings together strong software engineering skills with thorough quality assurance, so that its clients can deploy policy-aware retrieval systems, cut down on operational overhead, and keep a firm competitive advantage. Because of its steadfast dedication to technical excellence and the design of custom data architectures, Lexis Solutions has received special recognition from CIO Bulletin as one of the "Top Web Scraping and Data Services Companies 2027".
In an exclusive conversation with CIO Bulletin, Emil Kirilov, Co-Founder of Lexis Solutions, shared how his team builds mission-critical data pipelines, solves intricate web extraction challenges, and helps enterprises turn raw online intelligence into high-value strategic assets.
In Conversation with Emil Kirilov
How is Lexis Solutions preparing for the next wave of anti-bot defenses and dynamic website changes that will define web scraping success by 2027?
We design every scraper on the assumption that the site will change and push back. At Lexis Solutions, each source runs as an isolated scraper on a shared core, so a layout change or a block on one site never takes down the others. We pick the retrieval method per source: direct HTTP requests and lightweight parsing where possible for speed, and full browser automation with Playwright or Puppeteer where a site requires it, combined with managed proxy rotation and CAPTCHA handling.
The bigger preparation is monitoring. Our pipelines alert in real time on zero-yield runs, empty results, domain mismatches, and data anomalies, and we store execution history to spot when a site starts changing before it breaks. Increasingly, we use AI models to help adapt extraction logic when page structures shift, which cuts the time between a site change and restored data.
What unique strengths does your team bring to large-scale data extraction that help clients stay ahead in an increasingly competitive landscape?
Scale and maintenance experience. Lexis Solutions is an Apify partner with more than 300 public scrapers in the Apify Store, and on top of that, we run private client systems, some with more than 200 scrapers that our team monitors and maintains every day.
For a global coupon and promotions platform, we built infrastructure covering more than 100 websites across several countries and languages, storing millions of structured records and reducing manual data validation by 65%. For Pricerobot, a Scandinavian insurance comparison service, our system has run more than 75,000 car and home insurance price checks, returning comparable offers from multiple insurers in under 2.5 minutes per request. The same engineers also build AI systems, so the data we collect is shaped for how it will actually be used downstream.
In your view, what will separate the true leaders in web scraping and data services from the rest by 2027?
By 2027, extraction alone will be a commodity. The leaders will be the companies that keep data flowing for years, not weeks. That means isolated, well-monitored scrapers, validation that catches bad data before it reaches a client, and a team that treats maintenance as the main job.
The second differentiator will be what happens after collection. Clients increasingly want data that is already cleaned, matched to the right entities, and ready to feed an AI system or a dashboard. A web scraping company that can also build the AI and analytics layer on top will win over one that hands over a CSV file.
How is Lexis Solutions combining AI with traditional scraping techniques to deliver cleaner, more reliable data pipelines?
We use AI at the points where rule-based scraping struggles. The first is extraction from unstructured or inconsistent content. For Finansi.bg, Lexis Solutions processed more than 2 million company financial reports with very different layouts, using retrieval and Anthropic's Claude models to extract standardized figures, with fewer than 8,000 documents needing manual review.
The second is validation and matching. On a coupon platform covering more than 100 websites, automated checks on merchant identity, relevance, and consistency reduced manual validation work by 65%. The third is enrichment: at Onno Plus, reviews scraped daily from Google, Trustpilot, and Kununu are analyzed by AI to prioritize cases for the legal team. Traditional techniques still do the collection. AI makes the output cleaner and more useful.
Which emerging data privacy and compliance challenges do you see as most critical for companies operating in this space over the next few years?
Three areas stand out. Personal data in scraped content is the first: under GDPR, collecting names, reviews, or profiles requires a lawful basis, minimization, and clear retention rules, even when the data is publicly visible. The second is the use of web data to train or ground AI models, where EU copyright rules on text and data mining opt-outs and the transparency requirements of the EU AI Act are raising the bar for documenting where data came from. The third is website terms and database rights, which vary by jurisdiction.
Our approach at Lexis Solutions is to collect only the fields a client needs, document sources and purpose for every pipeline, prefer official APIs where they exist, and build the compliance review into project scoping rather than treating it as an afterthought.
How does Lexis Solutions ensure both speed and long-term reliability when building production-grade data collection systems?
Speed comes from reuse. Our scrapers share a common core of utilities for sessions, proxies, retries, and output formats, and new sources are onboarded from templates, so adding a new website is a fast, repeatable process. For performance-critical sources, we move from browser automation to direct HTTP requests once the target is understood, which is how the Pricerobot system keeps insurance comparisons under 2.5 minutes.
Reliability comes from isolation and visibility. Each source fails independently, multi-layer validation checks data before it is stored, and alerts go straight to the engineers responsible, with enough context to fix the issue quickly. Production data systems are long-term commitments, and we staff them that way.
Looking at the industries you serve, where do you expect the strongest growth in demand for advanced web scraping solutions by 2027?
The strongest growth we see is in three areas. Financial services and insurance, where price comparison and company data products depend on fresh, accurate data from many providers. E-commerce and retail, for pricing, promotions and fraud detection. And construction and preconstruction, where material prices, tenders and supplier data are scattered across hundreds of sources and feed directly into cost estimates.
Across all industries, the fastest-growing use case is feeding AI systems. Companies building assistants and agents need current external data next to their internal data, and that is where web scraping and AI integration meet.
What exciting developments or capabilities is your team working on that clients in the data services space should watch closely?
Three things. First, AI-assisted maintenance that detects when a site has changed and proposes updated extraction logic, shortening downtime across large scraper fleets. Second, speech-to-text and text processing at scale, turning recorded calls, meetings, and documents into structured, searchable data. Third, AI search visibility tracking: we built our own system that runs prompts across ChatGPT, Claude, and Gemini with simulated locations in different markets to measure how AI assistants describe companies and which sources they cite. As more buyers research suppliers through AI assistants, that kind of data is becoming as important as classic search rankings.
Meet the Visionary Leader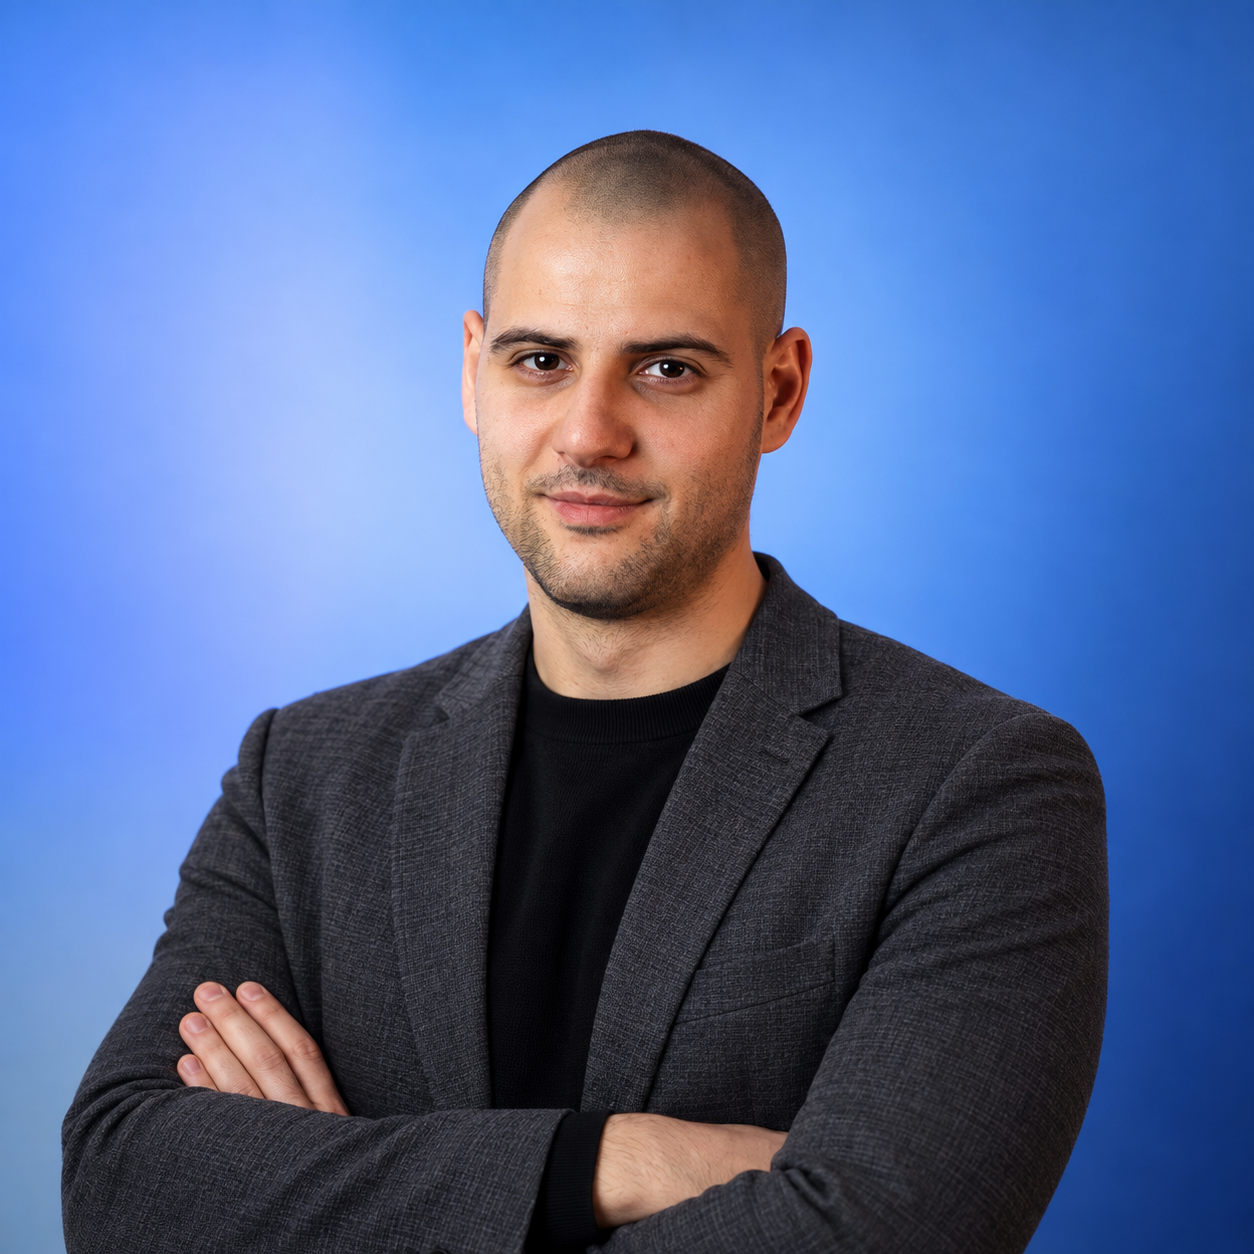
Emil Kirilov is a Co-Founder of Lexis Solutions (lexis.solutions) and leads its web scraping and data services team in Sofia. He manages the company’s in-house scraping engineers and its largest web scraping clients, overseeing production systems that run hundreds of scrapers, which are monitored and maintained every day. He was the lead architect and engineer behind two of Lexis Solutions’ flagship data platforms: Finansi.bg, which uses AI to extract financial data from Bulgarian trade registry filings for hundreds of thousands of companies, and Balans.bg, a legal and accounting knowledge platform built for Kreston BulMar. Emil holds the Claude Certified Architect certification from Anthropic.
Emil holds a bachelor’s degree in Software Engineering from the Faculty of Mathematics and Informatics at Sofia University. He began his career as a back-end developer at emerchantpay, a global payment service provider, working on payment integrations and transaction-heavy systems. At Lexis Solutions, he has designed data pipelines and parsers for some of the company’s most demanding sources, from a pipeline extracting yearly trade registry data for around 500,000 companies, to algorithms that turn hundreds of Bulgarian and EU legal acts, averaging 180 pages and up to ten levels of hierarchy, into structured, versioned and interlinked knowledge, to a marketing database for Bulgarian companies enriched with more than 30 additional data fields per company. He co-founded Lexis Solutions with three fellow students he met at the HackFMI hackathon in 2016.



 consultants ltd.jpg)


Comments